SlideServe
Menu
Préférences
© SlideServe · v2026

Motif finding methods and algorithms
khalil avatar
17 diapositives · 465 Views · Sep 14, 2014

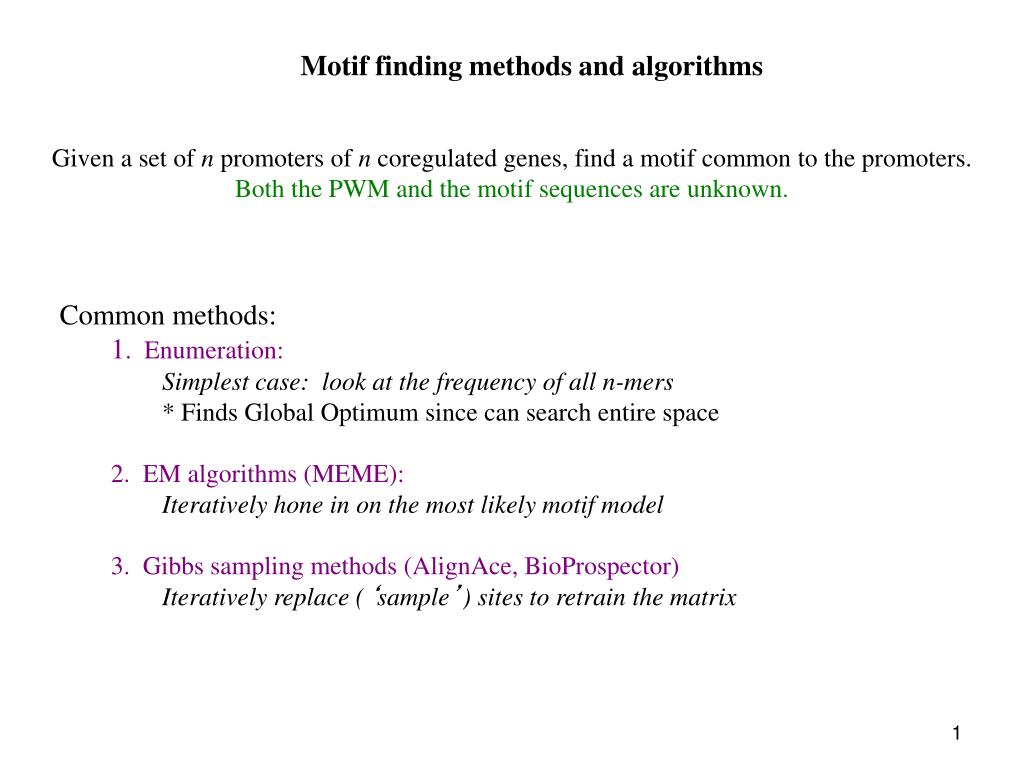
Motif finding methods and algorithms. Given a set of n promoters of n coregulated genes, find a motif common to the promoters. Both the PWM and the motif sequences are unknown. Common methods: 1 . Enumeration: Simplest case: look at the frequency of all n-mers
Motif finding methods and algorithms - slide 1
01 / 17Motif finding methods and algorithms
1 / 17

Télécharger la présentation

Motif finding methods and algorithms
Une image / un lien ci-dessous est fourni (tel quel) pour télécharger la présentation

Politique de téléchargement : le contenu du site vous est fourni TEL QUEL pour votre information et votre usage personnel ; il ne peut être vendu, concédé sous licence ni partagé sur d’autres sites sans l’accord de son auteur.Le contenu vous est fourni TEL QUEL, pour votre information et votre usage personnel uniquement. Téléchargez la présentation en cliquant sur ce lien. Lors du téléchargement, si vous ne parvenez pas à télécharger une présentation, l’éditeur a peut-être supprimé le fichier de son serveur.Pendant le téléchargement, si vous ne parvenez pas à obtenir une présentation, le fichier a peut-être été supprimé par l’éditeur.

F I N

Plus de contenu associé

Transcription de la présentation
  1. Motif finding methods and algorithms Given a set of n promoters of n coregulated genes, find a motif common to the promoters. Both the PWM and the motif sequences are unknown. Common methods: 1. Enumeration: Simplest case: look at the frequency of all n-mers * Finds Global Optimum since can search entire space 2. EM algorithms (MEME): Iteratively hone in on the most likely motif model 3. Gibbs sampling methods (AlignAce, BioProspector) Iteratively replace (‘sample’) sites to retrain the matrix

  2. New MEME tools: http://meme.ebi.edu.au/meme/intro.html (create your own Nth order markov background model) http://meme.sdsc.edu/meme/doc/fasta-get-markov.html

  3. Motif finding using the EM algorithm MEME (Bailey & Elkan 1995) http://meme.sdsc.edu/meme/intro.html • EM algorithm: Expectation-Maximization • In one run, trains the matrix model and identifies examples of the matrix MEME works by iteratively refining matrix and identifying sites: 1. Estimate motif model a. Start with an n-mer seed (random or specified) b. Build a matrix by incorporating some of background frequencies 2. Identify examples of the model a. For every n-mer in the input set, identify its probability given the matrix model 3. Re-estimate the motif model a. Calculate a new matrix, based on the weighted frequencies of all n-mers in the set 4. Iteratively refine the matrix and identify sites until convergence.

  4. Problem: find a 6-mer motif in 4 sequences S1: GGCTATTGCAGATGACGAGATGAGGCCCAGACC S2: GGATGACTTATATAAAGGACGATAAGAGATGAC S3: CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC S4: GATGACGGAGTATTAAAGACTCGATGAGTTATACGA 1. MEME uses an initial EM heuristic to estimate the best Starting-point matrix: G 0.26 0.24 0.18 0.26 0.25 0.26 A 0.24 0.26 0.28 0.24 0.25 0.22 T 0.25 0.23 0.30 0.25 0.25 0.25 C 0.25 0.27 0.24 0.25 0.25 0.27

  5. 2. MEME scores the match of all 6-mers to current matrix Here, just consider the underlined 6-mers, Although in reality all 6-mers are scored GGCTATTGCATATGACGAGATGAGGCCCAGACC GGATGACTTATATAAAGGACCGTGATAAGAGATTAC CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC GATGACGGAGTATTAAAGACTCGATGAGTTATACGA

  6. 2. MEME scores the match of all 6-mers to current matrix GGCTATTGCATATGACGAGATGAGGCCCAGACC GGATGACTTATATAAAGGACCGTGATAAGAGATTAC CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC GATGACGGAGTATTAAAGACTCGATGAGTTATACGA The height of the bases above corresponds to how much that 6-mer counts in calculating the new matrix Reestimate the matrix based on the weighted contribution of all 6 mers G 0.29 0.24 0.17 0.27 0.24 0.30 A 0.22 0.26 0.27 0.22 0.28 0.18 T 0.24 0.23 0.33 0.23 0.24 0.28 C 0.24 0.27 0.23 0.28 0.24 0.24

  7. MEME scores the match of all 6-mers to current matrix GGCTATTGCATATGACGAGATGAGGCCCAGACC GGATGACTTATATAAAGGACCGTGATAAGAGATTAC CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC GATGACGGAGTATTAAAGACTCGATGAGTTATACGA

  8. GGCTATTGCATATGACGAGATGAGGCCCAGACC GGATGACTTATATAAAGGACCGTGATAAGAGATTAC CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC GATGACGGAGTATTAAAGACTCGATGAGTTATACGA The height of the bases above corresponds to how much that 6-mer counts in calculating the new matrix Reestimate the matrix based on the weighted contribution of all 6 mers G 0.40 0.20 0.15 0.42 0.24 0.30 A 0.30 0.30 0.20 0.24 0.46 0.18 T 0.15 0.30 0.45 0.16 0.15 0.28 C 0.15 0.20 0.20 0.16 0.15 0.24

  9. MEME scores the match of all 6-mers to current matrix GGCTATTGCATATGACGAGATGAGGCCCAGACC GGATGACTTATATAAAGGACCGTGATAAGAGATTAC CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC GATGACGGAGTATTAAAGACTCGATGAGTTATACGA Iterations continue until convergence (ie. numbers don’t change much between iterations)

  10. Final motif G 0.85 0.05 0.10 0.80 0.20 0.35 A 0.05 0.60 0.10 0.05 0.60 0.10 T 0.05 0.30 0.70 0.05 0.20 0.10 C 0.05 0.05 0.10 0.10 0.10 0.35

  11. MEME uses final matrix to identify examples of motif by LLR S1: GGCTATTGCAGATGACGAGATGAGGCCCAGACC S2: GGATGACTTATATAAAGGACGATAAGAGATGAC S3: CTAGCTCGTAGCTCGTTGAGATGCGCTCCCCGCTC S4: GATGACGGAGTATTAAAGACTCGATGAGTTATACGA Final motif G 0.85 0.05 0.10 0.80 0.20 0.35 A 0.05 0.60 0.10 0.05 0.60 0.10 T 0.05 0.30 0.70 0.05 0.20 0.10 C 0.05 0.05 0.10 0.10 0.10 0.35

  12. Motif finding using the EM algorithm MEME (Bailey & Elkan 1995) http://meme.sdsc.edu/meme/intro.html • EM algorithm: Expectation-Maximization • In one run, trains the matrix model and identifies examples of the matrix Choice of parameters significantly affects the algorithm -- motif width w -- motif model: - “zoops” = zero-or-one motif per promoter sequence* - “oops” = one-or-more motif per promoter sequence* - “ans” = (“any number of sites”) two-component mixture model (ie. Each w-mer sequence is either an example of the background model or the motif model) -- background model: - simplest case: genomic nucleotide frequencies P(G,A,T,C) - nth-order Markov chain (eg. 2nd order Markov chain = P(Ai|Ci-1) = P(CA) = dinucleotide frequencies) *These models keep track of which input sequence (promoter) the motif came from, whereas ‘ans’ throws all “w-mers” into a bag

  13. Assessing the biological relevance of identified motifs Keep an eye on these features: 1. Bit score (or normalized bit score) Bit score = Information Content at each position 2. Information content profile Real TF binding sites typically show smooth IC profiles 3. Number of input sequences that contain the motif Overfitting: great looking motif but found in only few of the input sequences 4. Nucleotide frequencies Eg. In yeast, AT rich sequences are common … doesn’t necessarily mean they’re not real binding sites 5. Enrichment of motif in the training set compared to genomic bg Our old friend, the hypergeometric distribution. 6. Finding the same consensus with different models or methods 7. Any other nonrandom observation can give you confidence (palindromic motif, nonrandom distribution of motifs in input sequences, etc)

  14. Comparing matrices and motifs TomTom • Pick a scoring function • Calculate score for query matrix Q against ALL matrices in database • Use those scores to estimate a distribution of scores to turn score into a p-value • FDR turns p-value into an E value

  15. Comparing matrices and motifs Scoring functions: score each COLUMN being compared Column X of Motif Q vs. Column Y of Motif T 1 2 3 1 2 3 G A T C G A T C 0.3 0.7 0.3 0.1 0.6 0.4 0.1 0.1 0.1 0.1 0.1 0.1 0.5 0.1 0.3 0.7 0.2 0.4 0.1 0.1 0.3 0.1 0.1 0.1 Xa = P(base a) in column X of Q Ya = P(base a) in column Y of T

  16. Comparing matrices and motifs Scoring functions: score each COLUMN being compared Column X of Motif Q vs. Column Y of Motif T S P(base a) over all a == 1

  17. Alignment of two matrices Motif Q Column X = 1 … X = 14 Motif T Column Y = 1 … Y = 13