SlideServe
Menu
Préférences
© SlideServe · v2026

Mastering Cache-Friendly Programming Techniques

nettieharris avatar
5 diapositives · 78 Views · Jan 07, 2020

Learn about cache-aware and cache-oblivious strategies to optimize code performance and minimize cache misses. Explore examples like matrix multiplication and sorting arrays efficiently. Uncover Burstsort and C-burstsort algorithms for enhanced cache utilization.
Mastering Cache-Friendly Programming Techniques - slide 1
01 / 5Mastering Cache-Friendly Programming Techniques
1 / 17

Télécharger la présentation

Mastering Cache-Friendly Programming Techniques
Une image / un lien ci-dessous est fourni (tel quel) pour télécharger la présentation

Politique de téléchargement : le contenu du site vous est fourni TEL QUEL pour votre information et votre usage personnel ; il ne peut être vendu, concédé sous licence ni partagé sur d’autres sites sans l’accord de son auteur.Le contenu vous est fourni TEL QUEL, pour votre information et votre usage personnel uniquement. Téléchargez la présentation en cliquant sur ce lien. Lors du téléchargement, si vous ne parvenez pas à télécharger une présentation, l’éditeur a peut-être supprimé le fichier de son serveur.Pendant le téléchargement, si vous ne parvenez pas à obtenir une présentation, le fichier a peut-être été supprimé par l’éditeur.

F I N

Plus de contenu associé

Transcription de la présentation
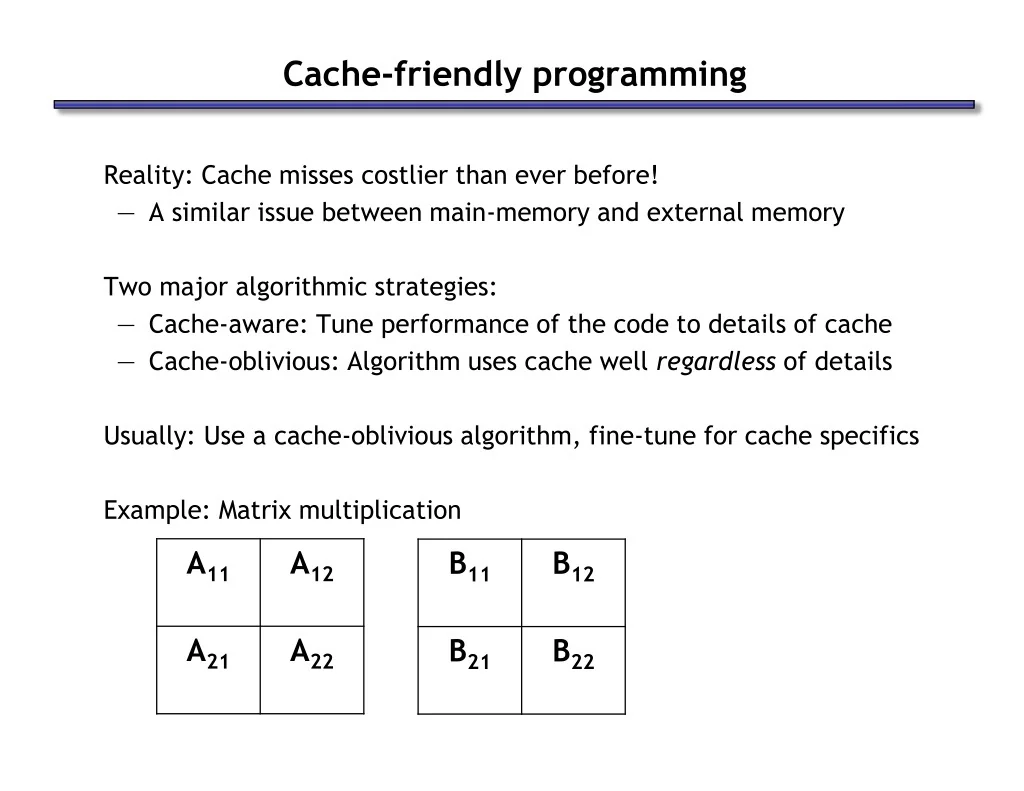
  1. Cache-friendly programming • Reality: Cache misses costlier than ever before! • A similar issue between main-memory and external memory • Two major algorithmic strategies: • Cache-aware: Tune performance of the code to details of cache • Cache-oblivious: Algorithm uses cache well regardless of details • Usually: Use a cache-oblivious algorithm, fine-tune for cache specifics • Example: Matrix multiplication

  2. Cache-friendly array layout • Recursively defined cache-friendly layout for array multiplication: • LAYOUT ( ) = LAYOUT ( ) LAYOUT ( ) …

  3. Sorting an array of strings • We could use Quicksort • but it is expensive to compare strings • A better (standard) option is Radix sort (similar to Bucket sort) • “Group” strings according to first letter • “grouping” using pointers, of course • Sort groups recursively using remaining letters • Can be viewed as a breadth-first exploration of a tree (actually, a trie): • This is slow because we: • access 1st letter of all strings • access 2nd letter of all strings • etc.

  4. Burstsort (Sinha and Zobel, 2004) • A burst trie is a trie in which overflowing buckets “burst” into several smaller buckets • Each string is processed in a linear, cache-friendly manner • this results in a depth-first traversal of the trie • When the string alphabet is large (256 for ASCII, grouped DNA letters), the trie is short and fat • depth-first traversal more cache-friendly than breadth-first traversal • upper level nodes remain in cache due to temporal locality • A problem with pointers: • when a bucket bursts, a new level needs to be created • all strings need to be accessed, which can lead to cache misses • Alternative algorithm C-burstsort (2006), stores unexamined tails of strings in buckets, instead of pointers

  5. MP6 issues, Final Exam